
Introduction
A transcript is a reporting aid, not a published quotation
A transcript can save a reporter from scrubbing through an hour of audio to find a passage. It cannot, by itself, establish that a quotation is accurate, fairly framed, on the record, or cleared for publication. Those judgments belong to the reporting and editing process. A recognizer turns sound into a candidate sequence of words; a journalist decides whether that sequence matches the voice, the context, and the agreed ground rules. The distinction matters most when a story turns on a short phrase, a negation, a number, a proper name, or a source’s qualification. An output may look coherent while shifting exactly the detail that changes the meaning. Procurement should therefore begin with the sentence the newsroom needs to verify and the action an editor must be able to take, not with a dashboard score or a long feature list. The distinction also helps a newsroom compare categories honestly. A meeting bot that captures speech while a call is happening is not automatically comparable to a post-recording service that receives a file later. A dictation tool optimized for one speaker is not necessarily a good fit for a two-way interview. State which workflow is under consideration, who initiates it, and whether the source knows how the recording will be processed. A short description of the assignment can expose a mismatch before procurement spends time on a feature-by-feature trial.
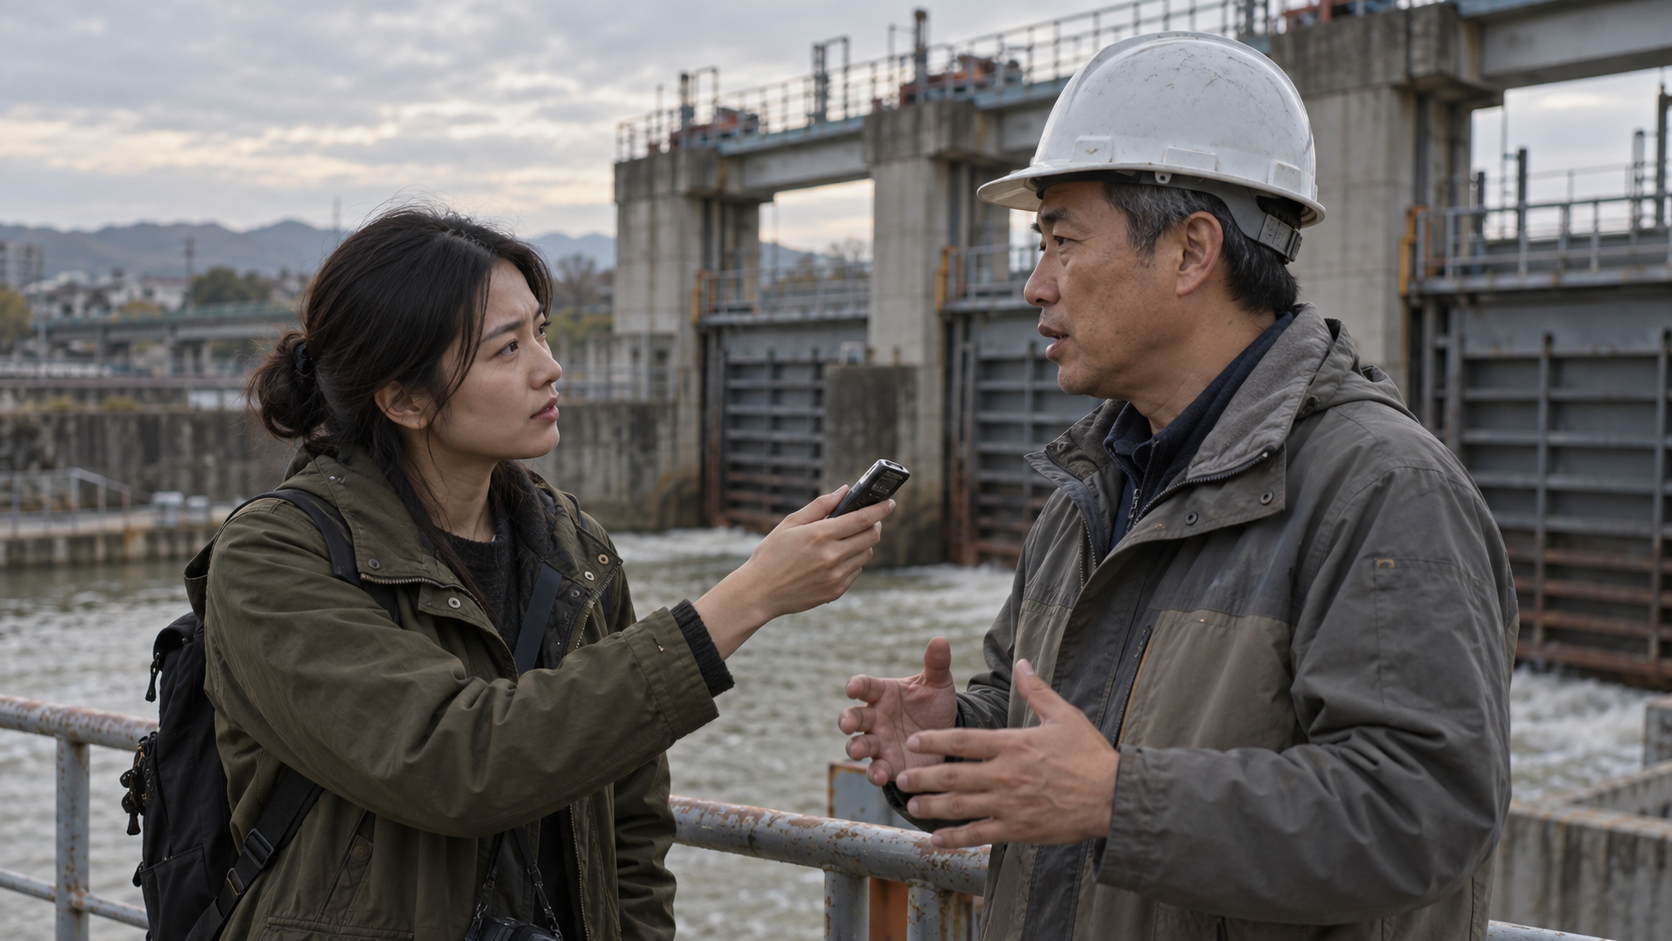
Imagine a reporter covering a proposed flood barrier and interviewing a neighborhood engineer. In the hypothetical recording, the engineer says that one gate “was not designed for a surge of that height,” then explains the model assumptions. A draft transcript drops “not” and marks a second voice as the engineer. A quick skim could turn a technical limitation into the opposite claim. A sound workflow lets the reporter open the exact recording span, listen to the full answer, confirm the speaker, and preserve the sentence before an editor sees it. It also keeps the raw transcript separate from a quotation edited for length or clarity. That chain—from audio to checked wording to approved copy—is what a newsroom is buying when it chooses a transcription service.
References: SPJ Code of Ethics, AP Statement of News Values and Principles (PDF).
Start with the deadline decision, not the tool category
The assignment determines the useful output. A daily briefing may need a searchable working transcript so a reporter can find candidate passages. A sensitive investigation may require a newsroom-approved processing route before any file leaves a controlled environment. A live broadcast may need captions under a different latency and review model. A long-form profile may require exact quote verification, clear speaker turns, and an editor’s record of changes. These are not interchangeable jobs. “Supports transcription” says little about whether the tool supplies the file type, timing, speaker labels, access controls, or review path the newsroom needs. Describe the next editorial decision in plain language: find the passage, verify words, confirm attribution, prepare a caption, or preserve an interview record. Then define what evidence the reporter needs to make that decision and who will sign off.
Keep the first pilot narrow enough to finish. The editor may select one completed, consent-cleared recording, a short segment, and two or three realistic tasks. The reporter marks where a key answer begins, verifies a quotation, and exports a checked excerpt to the desk. The standards editor confirms that source rules and permitted handling are met. The pilot records elapsed time, corrections, replay steps, failed exports, and any uncertainty left unresolved. It does not need to crown a universal winner. Its purpose is to identify which candidate can perform the newsroom’s actual job under its actual constraints, and which apparent convenience disappears once a person has to verify the result. If the test exposes a hard privacy or attribution failure, that is a useful answer even if the rest of the output looks polished. Set a practical acceptance rule before the first upload. It could require that every quotation selected for publication be replayable, that high-impact names and figures be corrected by a human, and that a checked copy reach the editor in the required format. The rule should name a person responsible for review and a point at which unresolved wording is escalated. Avoid thresholds that imply statistical certainty from a handful of excerpts. The pilot is a workflow test: it can show whether the desk can consistently complete its review, not guarantee the outcome of future assignments.
References: When is it OK to use anonymous sources?, Reuters: Accuracy and correction standards.
1. Define the Editorial Job Before Comparing Tools
1.1 Separate a working transcript from publication copy
A newsroom should label the raw machine output as a working transcript until a person has checked it against the recording. It may be useful for search and navigation without being suitable for quotation. A second file or clearly marked layer can contain reporter corrections; a third may contain copy edited for publication. These layers should not silently overwrite one another. If an editor changes a quote for length, punctuation, or readability, the record should still show what was heard and where the original passage sits. The label helps prevent a copy desk, producer, or fact-checker from mistaking a provisional sentence for approved language. It also gives the reporter a clear stopping point: the transcript can support discovery, but the words that enter the story still need the normal verification and approval process.
For the flood-barrier example, the working transcript might contain a candidate line, a timestamp, and a note that “not” needs replay. The reporter’s checked record can include the exact wording, a short span of surrounding context, the speaker’s confirmed role, and a link or locator to the authorized audio. Publication copy can then be edited within the newsroom’s quotation policy, with the original wording retained for comparison. Avoid attaching the source’s full name to a file when a restricted story code will do; keep any mapping in the approved system. This separation supports correction later. If a question arises after publication, an editor can trace the copy back through the checked quote to the recording, rather than relying on a smooth-looking transcript that may have been revised several times.
References: AP News Values and Principles, SPJ Code of Ethics.
1.2 Specify the quotation standard and transcript convention
“Verbatim” can mean different things in a newsroom. Some reporters preserve every filler, false start, and repeated word in the source record, while preparing a readable working copy for search. Others use a defined light-cleanup convention for routine quotations. Broadcast captioning, court reporting, archival interviews, and conversational research can require still different representations. The buyer should write down which details the intended workflow must preserve: disfluencies, interruptions, overlaps, pauses, laughter, code-switching, or vocal events that affect meaning. It should also state how to mark a span that cannot be understood. If the rules are left implicit, two editors may judge the same transcript differently, and a product that smooths speech may appear better merely because it hides its uncertainty.
A convention need not become a lengthy newsroom manual before a small test. One page can say how to handle contractions, punctuation, false starts, uncertain words, interviewer acknowledgments, and edited quotations. It can distinguish a transcript used to locate a passage from a record meant to represent speech closely. The pilot should then check those choices consistently across candidates. For example, if the newsroom keeps the complete phrase in a source record but removes a nonessential filler in published copy, the transcript and story draft should remain distinguishable. If a source’s pause changes the interpretation, it should not be silently converted into certainty. The point is not to preserve every sound in every story; it is to know which editorial decisions are allowed and to keep the transcript aligned with them.
References: AP Statement of News Values and Principles (PDF), TalkBank Jefferson transcription symbols.
1.3 Identify errors that could change a story
A single average score can obscure the mistakes that matter in reporting. List the high-consequence details for the assignment: negation, a name, a date, a measurement, a condition, a speaker change, or a phrase whose meaning depends on what came before it. A missed article may be harmless; a missed “not” may invert a claim. A number can be grammatically plausible but wrong by an order of magnitude. A sentence can be rendered accurately yet attributed to the wrong person. The newsroom should review these categories separately from general readability and mark what is a hard failure versus a correctable draft issue. This makes the pilot easier to interpret. A candidate that produces attractive prose but repeatedly obscures high-impact spans may be a poor reporting aid even if most ordinary words appear right.
The error list should come from the assignment, not from a vendor’s promotional checklist. For a planning-board story, dates, votes, conditions, and speaker roles may matter. For a source discussing an allegation, attribution, qualifiers, and surrounding context may be central. For a science interview, units, uncertainty, and distinctions between observation and explanation deserve attention. Do not use a hypothetical checklist as proof of performance; use it to create a consistent review. The editor can label each correction as low, moderate, or story-changing, then compare the correction burden across candidates. A reviewer should be allowed to mark “uncertain” rather than force a guess where the audio itself is unclear. This preserves the distinction between a transcription failure and an unresolved source recording.
References: AP News Values and Principles, Reuters Journalistic Standards.
2. Build a Journalism-Specific Evaluation Sample
2.1 Sample the conditions the newsroom actually records
A test file should resemble the assignment’s sound, not an idealized studio sample. Choose material that reflects the microphones, rooms, calls, field conditions, and speaker patterns reporters use. A street interview near traffic, a remote call with compression, and a quiet one-person statement can stress different parts of a workflow. Include the full range only if the newsroom expects to process it; an elaborate test is not automatically a better one. Record what the sample contains and why it was chosen. If the story depends on one technical phrase or a difficult proper name, include that stretch. If overlapping speech is common in a public meeting, include an overlap. A candidate tested only on a clean monologue cannot establish how it will handle the noisier assignments for which the desk may later rely on it. Build the sample from the reporting mix rather than choosing the cleanest file in the archive. If the desk routinely receives phone interviews, field recordings, and remote calls, select one authorized excerpt from each relevant condition or state clearly which condition is out of scope. A compact test might cover a quiet exchange, a noisier passage, a proper name, a number, and a turn change; the selection should reflect the actual desk rather than a universal recipe. Record why each passage is present so a later editor can tell what the test did and did not cover.
WhisperAITranscribe, an online audio and video transcription tool, can be included as one candidate, but its category alone does not resolve a newsroom’s editorial or data-handling requirements. The hypothetical reporter can select a short, authorized excerpt with a measured answer, a question from the interviewer, a location name, and a brief interruption. The same exact file, duration, channel mix, and settings should be used for every candidate. Preserve a copy of the input and note any conversion or trimming. If one provider requires a different processing route, document that as part of the candidate instead of pretending the route is identical. Do not remove a difficult section because one service fails on it; record the failure and determine whether it was a file, configuration, or service limitation. A small, representative sample is more valuable than a long collection with no defined review plan. The test should be repeatable by another editor who has not seen the first results.
References: CPJ Digital Safety Kit for Journalists, Reporters Recording Guide.
2.2 Treat diarization and real identity as separate questions
Speaker diarization groups stretches of audio that appear to come from the same voice. It does not tell a newsroom that a voice belongs to “the city engineer,” “the anonymous source,” or a named person. A label such as Speaker 1 is a provisional acoustic grouping. A journalist still has to confirm the role from the recording and reporting record. This distinction is easy to miss when an interface uses labels that look authoritative. The pilot should score whether the tool marks speaker turns consistently and separately note whether the human can map those turns to verified participants. If a speaker label is important to the story, review the transitions rather than merely checking whether the output contains labels.
Include the conditions that matter: a short acknowledgment from the reporter, a speaker who trails off, an interruption, a second person entering, or two voices speaking over each other. A test can record split turns, merged voices, missed interjections, and time needed for a reviewer to fix them. If a service offers channel separation and diarization, test them as separate capabilities; stereo channels do not necessarily correspond to named speakers, and diarization labels do not prove identity. Keep any mapping from provisional labels to real people in a restricted location if the source rules require it. Do not put a confidential source’s identity into a test filename or exported transcript simply because it makes evaluation convenient. The reporting record should explain how a role was confirmed and who is allowed to see the mapping.
References: Amazon Transcribe speaker diarization, Google Cloud Speech-to-Text recognize method.
2.3 Include names, numbers, accents, and code-switching
A general sample can miss the terms most likely to matter in a particular story. Add names, unfamiliar places, specialist vocabulary, dates, measurements, and language switches that occur in the assignment. A spelling that looks plausible may still refer to the wrong person or institution. A number without its unit may be incomplete; a decimal may change the scale. If the interview includes a phrase in another language, test that phrase under the configuration the newsroom expects to use, not under a setting selected after seeing the output. Document the language, equipment, and conditions. Do not assume that automatic language detection or a broad language-support list establishes performance on the specific dialect, accent, or code-switching pattern in the recording.
The reporter should build a small, lawful evaluation list from material the newsroom is permitted to use. It might include a public place name or technical term, but it should not contain a confidential source’s identity unless that use is authorized. Ask whether a provider accepts a custom vocabulary and what happens to any terms supplied. Then confirm the output against the recording and keep corrections separate from the raw transcript. If a misspelling changes a person’s identity, treat it as a significant correction even when the rest of the sentence is readable. If the audio does not support a confident spelling, mark it unresolved and check with an appropriate source rather than letting the recognizer settle the question. For multilingual work, include a reviewer competent in the language; a transcript that no reviewer can validate is not ready for quotation.
References: CPJ Protecting Confidential Sources, UK Data Service anonymisation for text data.
3. Compare Output Against a Human-Checked Reference
3.1 Prepare a reference that follows newsroom rules
A useful comparison starts with a reference transcript reviewed against the audio under the same convention the newsroom expects. It should identify the relevant speakers, preserve the required wording, and mark genuinely uncertain spans. A second transcriber or editor can independently review the difficult passages and record how a disagreement was resolved. Do not treat one candidate transcript as ground truth for all the others. Nor should the reference be polished so heavily that it hides the phenomena the newsroom wanted to test. If the newsroom intends to use machine output only to find a quote, the reference may focus on the passages and distinctions that drive that task; it still needs enough surrounding context to judge whether the quote is fairly represented.
The reference is not a claim that every word in every recording can be known with equal confidence. A muffled name may remain unclear after replay. A speaker may interrupt another and leave the grammatical sentence unfinished. The reviewer can record alternatives, confidence, and what additional evidence might resolve the question. Use the newsroom’s chosen spelling and punctuation rules consistently, and document whether fillers or repeated words count as differences. That makes the comparison explainable to the editor who reads it later. If the reference has a mistake, the score will reward or penalize candidates incorrectly; review the high-impact spans twice before relying on a metric. Keep the source recording, reference, and raw outputs connected by a restricted project identifier rather than a public story slug when the source is sensitive.
References: NIST ASR Metrics: Word Error Rate, UK Data Service example transcription instructions (PDF).
3.2 Hold the file and settings steady across candidates
For the comparison to be useful, freeze the test conditions before listening to results. Record the exact authorized file, audio duration, channels, candidate service and route, language choice, model or configuration when visible, diarization setting, vocabulary option, date, and output type. A web upload page, a developer API, a human transcription service, and a built-in meeting assistant are different candidates. They may handle data differently and produce different outputs. If the newsroom is evaluating a second configuration, label it as another test rather than quietly replacing the first result. Store the original input read-only and keep each raw output before any reporter correction. That gives the editor a way to reproduce a disputed comparison and see what the candidate actually returned.
The same discipline applies when a service fails. Record whether the upload was rejected, the format was unsupported, processing timed out, or an output was missing. Note the file and configuration rather than swapping in a cleaner segment only for that candidate. If the vendor documentation describes a setting, verify that the option exists in the actual account and regional route being considered; documentation may describe a different service tier or API. Each route should be checked against newsroom policy before sensitive material is sent. For a practical pilot, a spreadsheet or a small internal record can hold candidate names, setup, elapsed time, error notes, and reviewer disposition. The test should not collect source details beyond what is needed to make the selection, and access to the comparison record should follow the same restrictions as the audio.
References: OpenAI transcription guide, Google Cloud Speech-to-Text recognize method.
3.3 Use word error rate as a diagnostic, not quote approval
Word error rate is commonly calculated as substitutions plus deletions plus insertions divided by the number of words in a reference. It can summarize how two transcripts differ when both have been normalized consistently. It cannot decide whether a quotation is fair, whether a source’s meaning has been changed, or whether an unclear voice has been attributed correctly. A sentence with one missing negation can be consequential even when the overall score is low; dozens of harmless punctuation or filler differences can raise a score without changing the central claim. If a newsroom reports a metric, include the denominator, normalization rules, sample length, and unresolved words. Do not convert one short recording’s score into a universal accuracy promise.
The metric is most useful when it leads to a specific question. Did one candidate miss names but otherwise perform similarly? Did another preserve more words but require extra cleanup? Were the differences concentrated in a noisy section? Keep those findings next to a short list of high-impact errors and the reviewer’s time. In a pilot of three excerpts, a single difficult surname can dominate a small denominator; the editor should inspect the raw examples before ranking candidates. If the task is finding candidate quotes, measure how often the reviewer can locate and verify the passage, not just how many tokens match. If the task is captions, use the newsroom’s caption review standard. The score should help focus human review rather than replace it. WhisperAITranscribe belongs on a shortlist only if its actual route fits the newsroom’s approved handling and output needs; this article provides no measured comparison of it or any other provider.
References: NIST ASR Metrics: Word Error Rate, Reuters Journalistic Standards.
4. Evaluate Review, Deadline, and Publication Handoff
4.1 Keep every candidate quotation traceable to its audio
A transcript becomes useful to an editor when the disputed sentence can be found again quickly. Test whether a reviewer can move from a candidate quote to the corresponding point in the recording, hear the preceding and following context, and confirm the speaker. A timestamp can help, but the workflow should identify whether it is attached to a word, a sentence, or a rough segment, and whether it remains aligned after edits. If the transcript has no direct playback, use a stable time locator or another controlled reference to the source file. Test a name, a short statement, and one passage where a qualification changes meaning. The goal is not to make every transcript interactive; it is to ensure that the newsroom can reconstruct how a quotation was checked.
The reporter’s note should preserve more context than the final quote. A source might answer “only under those conditions” after a question that defines the scope; removing the question can make the words appear broader. A transcript search result may show a few lines around a term, but the editor still needs enough audio to judge tone, sequence, and whether another speaker intervened. Test what happens when the candidate is edited: does the time locator still reach the original audio, or does it point to a changed draft? If files move between a reporter’s laptop and the assignment desk, keep a stable identifier and preserve the raw version. A reporter should verify those requirements on the route being considered rather than assuming that a timestamp or playback control can be preserved after edits.
References: AP News Values and Principles, WebVTT: The Web Video Text Tracks Format.
4.2 Measure correction effort under a real deadline
A transcript can be fast to produce and slow to make publishable. A pilot that includes WhisperAITranscribe should measure the work a reporter and editor actually perform: listening to the file, correcting words, confirming speakers, replaying quotations, checking names and numbers, exporting copy, and returning questions to the source when policy permits. The useful number is not simply minutes until the first draft appears. It is the total time from an authorized recording to the newsroom’s checked deliverable, including any waiting or rework. If the desk’s deadline is 4 p.m., run the pilot on a schedule that reflects the available review window, but do not expose a source recording merely to simulate speed. One controlled, approved sample can show where an interface makes corrections easy or where it forces a reviewer to switch between tools.
Keep a correction log with categories rather than only an overall grade. Count story-changing errors, routine spelling or punctuation fixes, speaker corrections, uncertain spans, and time spent in replay. Note whether one editor can review the transcript, or whether another person must reconstruct what happened. A high raw word match may still produce heavy correction effort if the candidate output is hard to navigate. Conversely, a transcript with some visible errors may be useful if every quote can be found quickly and corrected without losing the source. The hypothetical flood-barrier reporter can time the search for the engineering caveat, not just the upload. That makes the evaluation relevant to deadline work. Keep the metric simple enough for the desk to repeat; a pilot that requires a separate analyst for every story is unlikely to become newsroom practice. A simple workload calculation can keep the decision grounded: count the reporter’s setup time, first-pass listening, corrections, quote replay, editor review, export cleanup, and any administrative work required to keep access controlled. Add the service cost only after the work units are visible. The same calculation can be repeated for each candidate under the same assignment conditions. Do not price the reviewer’s time as zero just because it happens after the upload. If a candidate saves a few minutes of typing but adds repeated searching or speaker repair, the net effect may be negative for the desk.
4.3 Test the export into the desk’s next step
A transcript may look acceptable in a browser but fail at handoff. A newsroom evaluating WhisperAITranscribe should verify the actual export in the account and route under review, then record what survives the handoff. Test the export the newsroom would actually use: a document for an editor, a caption file for video, a searchable text copy, or another format required by the assignment. Check whether timestamps, speaker labels, paragraph breaks, punctuation, and the original wording survive. Inspect how the export opens on the desk’s supported software and whether the editor can preserve a distinction between raw output and checked copy. If metadata or filenames contain source details, remove or protect them according to policy. Do not assume an export preserves an interactive locator, access restriction, or correction history unless the exported file demonstrates it.
The handoff should name an owner. A reporter may deliver checked quotes and locators; a producer may prepare captions; an editor may approve publication text; a records editor may retain the interview under a different schedule. These are separate duties. A file type that works for one may not suit another. Verify the required formats on a harmless, authorized sample, then document what is lost when the file is converted. For subtitles, check timing and line display in the destination player. For a fact-checking handoff, include enough source context for the reviewer to confirm the sentence without sending the full recording to people who do not need it. Confirm the specific export and access behavior in the intended account; a category description does not prove compatibility with the newsroom’s publishing or archive system.
References: WebVTT specification, OpenAI transcription endpoint reference.
5. Protect Sources and Recordings Before Upload
5.1 Confirm ground rules, consent, and newsroom policy
Before an audio file leaves the recorder, confirm that the interview was obtained under ground rules the reporter can explain. “On background,” “off the record,” anonymity, and attribution arrangements need clear definitions agreed in advance; a transcription service cannot determine them after the fact. Check the newsroom’s policy on where recordings may be processed, who can access working copies, and whether a source or subject was promised a particular form of handling. Recording-consent rules vary by jurisdiction and circumstances, so a product comparison should not substitute for current legal advice from the newsroom’s counsel. A technical workflow cannot cure an unclear agreement or retroactively expand what the source permitted. Write down the source agreement as the reporting team understands it, including the permitted attribution and the boundary on reuse. If an interview is on background, the newsroom should know what that means in its own policy and what was agreed with the source. A transcript may be shared with an editor who is part of the reporting process, but that does not automatically authorize sending the full file to an outside service. The person who approves the route should consider the promise made to the source and the actual access path, not merely whether the tool has a privacy statement.
Treat approval as a gate, not a score that can be offset by convenience. A candidate route may be excluded if the organization has not approved it for the recording’s sensitivity, if it crosses a boundary the newsroom cannot accept, or if the reporter cannot explain how access is controlled. Where policy permits a test, use the least sensitive authorized material that still represents the task. Record who approved the sample and where the output may be stored. Do not send an interview to a free trial or personal account without checking the applicable terms and newsroom rules. Confirm the exact route, current terms, and your organization’s approval before any real source audio is uploaded.
References: Reporters Recording Guide, SPJ Code of Ethics.
5.2 Treat voice, context, and metadata as identifying information
Removing a name from a transcript does not necessarily make it anonymous. A voice may be recognizable to a small community. A combination of job title, location, dates, family details, or a distinctive event can point to one person even when no name appears. The recording may also contain background voices or identifying sounds that the written copy omits. Think about the source, the people mentioned, and any person who entered the recording without being the interview subject. Restricting access to the transcript while leaving the audio in a shared folder can defeat the intended boundary. A newsroom should consider the full file and its surrounding context, not just the names in the text. Identification risk is cumulative. A transcript may omit a name yet retain a job title, a meeting date, a small location, and a distinctive sequence of events; together, those details can narrow the person to one likely source. A voice recording adds qualities that a text export cannot remove. Consider whether the interview includes incidental speech from family members, colleagues, interpreters, or bystanders, and whether their words are necessary for the task. A de-identified working copy should be reviewed for context clues, while the original audio remains protected under the newsroom’s source-handling rules.
Metadata and derivative copies need the same attention. File names, account identifiers, cloud history, sharing links, local caches, and backups can reveal who made or received an interview. A quote may be safe to show an editor while the full audio remains restricted. A redacted excerpt can still contain a rare detail that identifies its speaker. Create a sharing copy for the recipient’s task and avoid distributing the raw file by habit. WhisperAITranscribe should be evaluated under the same source-identification questions as any online transcription route; the fact that it handles audio and video does not demonstrate a particular anonymity or source-protection control. Test with authorized material and ask the provider for documented answers about the route you would use. The newsroom remains responsible for deciding whether those answers fit its source commitments.
References: CPJ Digital Safety Kit for Journalists, NIST Guide to Protecting the Confidentiality of Personally Identifiable Information.
5.3 Verify access, retention, and deletion for the chosen route
“Secure” is not a complete procurement answer. Ask what data the chosen route receives, where it is processed, who can access it, whether it is used for service improvement, how long input and output remain, and what deletion covers. A provider’s consumer interface and API can have different terms or controls; a public documentation page may describe only one route, region, or account type. Record the URL and date of the answer, and have the newsroom’s privacy or security owner review it. Confirm whether the same rules cover transcripts, audio, logs, support tickets, and backup copies. If an answer is missing or too broad, keep the recording outside that route until the responsible editor resolves the issue. When a shortlist includes WhisperAITranscribe, ask for the same route-specific details you request from every other provider. Preserve the exact answer relevant to WhisperAITranscribe alongside the account type, region, and date, and do not substitute a general product description for current processing terms.
Ask practical questions about account ownership, multifactor authentication, role-based access, link sharing, export, deletion confirmation, and what happens to a file after a user closes the page. Check whether a retention setting is available for the actual subscription and whether the newsroom can administer it centrally. “Delete” may mean removing a visible file while copies remain subject to another schedule; obtain a specific explanation rather than inferring behavior. A controlled pilot can use a non-sensitive sample to observe the interface, but it cannot establish unseen retention practices. Keep written answers with the procurement record and revisit them when the route or terms change. Do not treat a vendor’s general trust page as a substitute for an account-specific review. For a newsroom considering WhisperAITranscribe, the questions remain practical: which users can access a file, how long it remains available, and what deletion covers. Record what you can verify and mark anything else unresolved rather than inferring a control from the service category.
6. Conclusion
6.1 Apply hard gates before weighted scores
Start by excluding routes that cannot satisfy the newsroom’s editorial or handling requirements. A candidate must be permitted for the recording, preserve enough evidence for a reporter to verify wording, give the editor a workable attribution and review path, and support the handoff the assignment needs. Those are gates. No speed advantage or low cost should compensate for a route the newsroom is not allowed to use or for an output that cannot support the required verification. Among the candidates that pass, compare the work that remains: correction time, replay, speaker review, export, account administration, and service cost. A scorecard is useful after the gates because it makes tradeoffs visible; before them, a high total can hide a disqualifying risk. WhisperAITranscribe should be evaluated against the same sample, permissions, and review criteria as every other candidate.
The decision record should be short enough to use again. Name the assignment type, approved sample, test conditions, high-impact errors, review minutes, unresolved risks, and person responsible for sign-off. State what the score cannot tell you: a small sample is not a general accuracy guarantee; a speaker label is not identity confirmation; a vendor’s written policy is not proof of every operational detail; a transcript is not publication approval. The next editor should be able to reproduce the key checks or understand why the newsroom accepted the remaining limitations. No brand name is a substitute for testing the work the newsroom actually needs.
6.2 Run a four-step newsroom pilot
Step 1: Write the assignment’s transcript job, source restrictions, quote standard, and high-impact error list. Step 2: Choose a short authorized recording that reflects expected field conditions; include WhisperAITranscribe in the comparison only if the specific online route has been cleared for that material. Step 3: Run each approved candidate with the same file and documented settings, then compare against a human-checked reference while recording corrections, replay, attribution fixes, and elapsed review time. Step 4: Export the checked deliverable to the desk’s actual next step, verify the handoff, and have the responsible editor decide whether the remaining limitations are acceptable. The pilot should answer one concrete procurement question, not produce an abstract winner. If a hard gate fails, stop that candidate’s evaluation and preserve the evidence that explains why.
Keep the pilot small and repeatable. A desk can use a second excerpt when the first sample does not represent the assignment mix, but it should say what new condition the second file tests. Preserve the original inputs and raw outputs under approved access rules; do not keep copies indefinitely simply because they were used in an evaluation. Where a service route or contract changes, repeat the parts of the review affected by that change. Where no provider meets the gates, use the newsroom’s established process while procurement continues. The decision can be “not suitable for this class of recording,” rather than “bad tool.” That narrow conclusion is more useful to a reporter and less likely to be mistaken for a universal product ranking.
6.3 Choose a workflow the newsroom can defend
The best choice is the candidate that fits the reporting task and leaves a clear path from a sentence in the story back to the source that supports it. That path includes an authorized recording, a provisional transcript, a human check, a confirmed speaker, enough context to assess the quotation, an editor’s approval, and a controlled handoff. If the workflow omits one of those steps, the newsroom should know which person owns the gap. It should also retain a correction process: if a quote is challenged, the editor can retrieve the source, reconstruct the decision, and correct the story when needed. The value of transcription is time returned to reporting, but only after accounting for the review required to make the result trustworthy. For a small desk, WhisperAITranscribe may be one candidate to assess as an online audio and video transcription tool; a broader comparison should include other routes the newsroom is authorized to test. A newsroom considering WhisperAITranscribe should base the decision on the same verified handling terms and pilot evidence required of every candidate. The choice should rest on verified handling terms and the pilot’s observed correction work, not on a generic claim of accuracy or confidentiality. If the newsroom cannot verify a key setting or export, leave that point unresolved and keep sensitive recordings out of the route. At the end of the pilot, document the scope: which recording conditions were represented, what the team checked, and what remains unknown. That honest boundary lets a future editor extend the test without treating a narrow newsroom decision as a claim about every assignment or source.
References: AP News Values and Principles, CPJ Protecting Confidential Sources.