
Introduction: Defining the Bilingual Deliverable
The Current Landscape of Multilingual Recorded Content
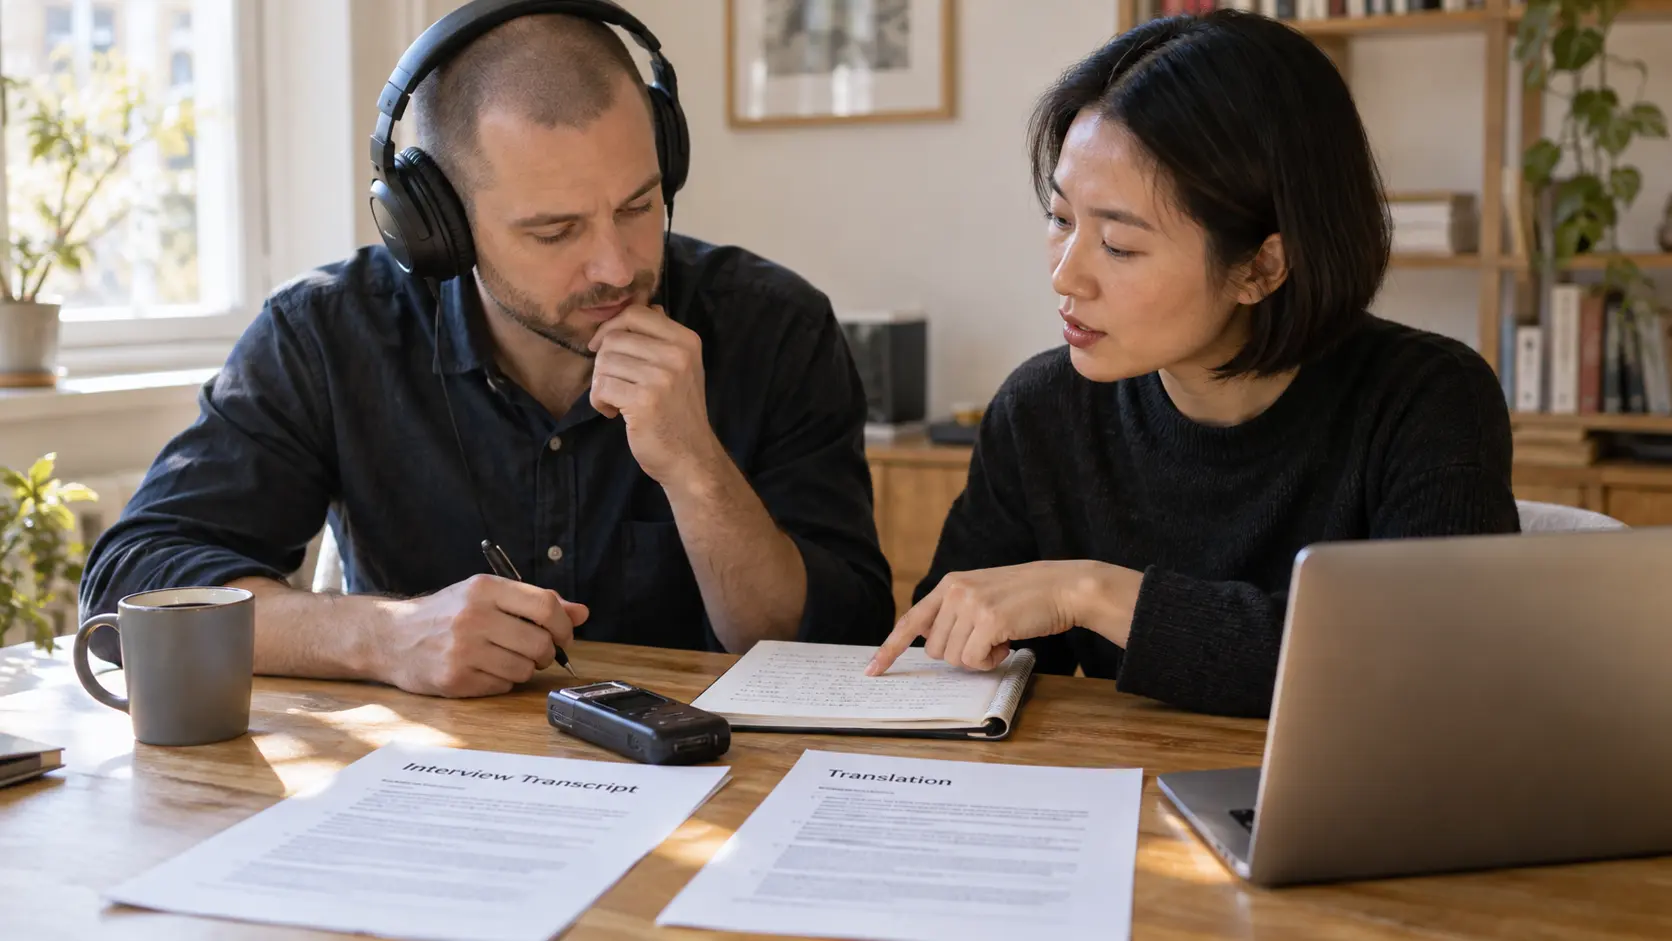
An international interview or training recording can generate several useful outputs: an original-language transcript, a translated reading version, and synchronized subtitles for another audience. These are related, but they are not interchangeable. A researcher checking what was actually said may need the original wording, while a course participant needs meaning in an accessible language. Keeping the source recording and each derived output identifiable allows both needs to be met. Without that separation, a polished target-language sentence can be mistaken for a literal quotation from the recording, or a source-language spelling error can become invisible after translation.
A good starting point is a named deliverable and reviewer. Specify who will use the text, whether quotations must remain verbatim, whether timing must be preserved, and who can assess the language pair. For a hypothetical Spanish interview containing English technical terms, the first decision is not the final export format. It is whether the team needs faithful Spanish text, an English interpretation, or both. That decision shapes testing, editing, and the record that accompanies the finished material.
References: W3C: Planning Media Alternatives and Other Languages.
Why Task-Specific Evidence Matters in 2026
Useful comparisons separate recognition quality, translation quality, and reporting conventions. FLEURS supplies multilingual speech data for tasks including recognition and language identification, while Matt Post’s BLEU reporting paper explains how evaluation configurations affect comparability. Together, these sources illustrate why the task, data, and measurement setup must remain attached to a score. A multilingual benchmark is not a test of every professional recording, and a translation score cannot be substituted for a source-transcript error rate. The evaluation question should match the output the reader needs.
The practical objective is a reproducible bilingual review. Preserve the tested audio, a checked source reference, any target reference, and the treatment of names, punctuation, and mixed-language passages. Record who reviewed meaning as well as what the metric measured. This makes later revisions understandable: an improved score may reflect a different preprocessing convention, a better transcript, or a better translation. Those explanations should not be collapsed into a single claim that one tool is universally more accurate.
References: Google FLEURS: Multilingual Speech Dataset; ACL: A Call for Clarity in Reporting BLEU Scores.
1. Understanding Multilingual Speech Tasks
1.1 Language Identification, Transcription and Translation
The workflow begins with language identification, then defines recognition or translation according to the task. Source-language text records the speech, while target-language text is a derived expression of its meaning. A language pair describes the intended direction, and task settings establish what the system should return. Microsoft’s language-identification documentation distinguishes detection modes; Hugging Face’s translation guide treats translation as a separate text task. Neither makes the stages equivalent. Detecting a language is not proof that its words were recognized correctly, and recognizing words is not proof that their meaning survives a later language change.
Preserve the distinction in the output record. In the hypothetical interview, retain the original passage and label the English version as a translation. A reviewer can then identify whether a wrong conclusion began with misrecognition or with interpretation. Without the source text, a translator may be asked to fix a statement that was never accurately captured. Separating the stages does not require separate products, but it does require clear responsibilities and evidence for each result.
References: Microsoft: Language Identification Concepts; Hugging Face: Translation Tasks.
1.2 Model Tasks and Output Conditions
Model behavior depends on task selection, language conditioning, text decoding, model capability, and output requirements. Whisper’s encoder–decoder architecture maps audio representations to output text under task conditions. This helps explain why the same recording can be used for different tasks without making their results interchangeable. The reviewer should know whether the output aims to retain wording, change language, or organize content afterward. A product label containing a model’s name is not enough to identify its checkpoint, runtime, or the settings used by a hosted service.
The useful question is what can be confirmed for the actual workflow. If a service exposes a language choice, record it. If it does not disclose its private model configuration, evaluate observable results rather than inventing a backend explanation. Check the original-language output before relying on a derived translation for quotations. This creates a task-level account of quality even when implementation details are unavailable, and prevents external model documentation from being mistaken for proof of a product’s internal system.
References: Hugging Face: Whisper Model Documentation.
1.3 Multilingual Data and Representative Evaluation
Evaluation should examine language distribution, recording conditions, domain vocabulary, reference preparation, and sample coverage. FLEURS documents speech tasks and dataset splits, including distinct speakers across training and evaluation sets. Its role here is to illustrate controlled evaluation, not to replace testing on a team’s materials. A workshop with technical abbreviations, audience interruptions, or accented speech may pose different challenges from a prepared benchmark. Select samples that reflect the intended use and state what they do not cover, so that a broad language label does not conceal a narrow test.
Keep language groups visible in the results. A single average can obscure a weak subgroup that matters to the audience. Review original-language accuracy and translation meaning separately for each relevant scenario, then describe the workload behind any aggregate. When revising the sample, preserve the previous version rather than silently replacing difficult passages. This allows a genuine workflow improvement to be distinguished from a more convenient evaluation set and gives future reviewers a consistent comparison point.
References: FLEURS: Supported Tasks and Dataset Splits.
2. Capabilities That Need Separate Verification
2.1 Source Accuracy and Translation Fidelity
Evaluate word errors, character errors, semantic fidelity, editing effort, and final usability as distinct dimensions. WER and CER compare recognition output with a reference at different units, as described in Hugging Face’s evaluation material. Neither directly scores whether a target-language sentence preserves a speaker’s condition or degree of certainty. The task therefore requires more than choosing the smallest recognition error rate. A name corrected in the source may improve all later outputs, while a target-language ambiguity requires someone who understands the intended meaning to review it.
WhisperAITranscribe (an online audio and video transcription tool) can provide editable text from recorded audio or video, with language selection as part of its public workflow. Its useful role is creating a reviewable source record that the team can inspect before relying on derived material. Establish which words, numbers, and attribution points need checking, then evaluate any translation stage on its own terms. This does not turn an external model score into a product benchmark or imply that every downstream language task is already supported.
References: Hugging Face: ASR Evaluation Metrics.
2.2 Language Coverage, Accents and Code-Switching
Distinguish supported languages, supported tasks, locale choices, accent conditions, and code-switching behavior. Microsoft’s language-support documentation separates capabilities by speech workload. That organization demonstrates why a language listed for one function does not establish every other function. A team should check the specific source and target requirements rather than treat a headline language count as a complete compatibility matrix. Mixed-language speech also needs its own representative passages: a recording in one dominant language with borrowed technical terms is not necessarily the same problem as several speakers alternating languages.
In the hypothetical Spanish interview, mark passages containing English product terminology, abbreviations, and a change of conversational language. Review those passages as their own group instead of assuming ordinary Spanish results describe them. Check whether proper names remain intact, whether the output unexpectedly changes language, and whether a later translation interprets the borrowed phrase correctly. These are test observations to collect, not guarantees attached to a multilingual label or reasons to replace unfamiliar terms with more common words.
References: Microsoft: Language Support by Speech Capability.
2.3 Timestamps and Attribution Across Language Versions
Keep source timing, translated wording, speaker labels, and identity evidence distinguishable. A translated sentence can have a different length or order from the spoken version, while timestamps still refer to the original media. WhisperX documentation separates alignment and diarization concerns. The workflow consequence is that fluent target text does not establish precise word-level correspondence or a verified speaker name. A reading translation may use broader passage links, while synchronized subtitles need a presentation decision that fits the audio and preserves the intended meaning.
For an interview excerpt, first establish who spoke and where the passage occurs. Then have the language reviewer confirm the translation without allowing a convenient subtitle split to change attribution or remove a condition. If the audience only needs paragraph-level navigation, do not imply a word-by-word timing guarantee. The record should make the chosen granularity visible, allowing another reviewer to trace the translated statement to the source passage without reconstructing an undocumented alignment process.
References: WhisperX: Alignment and Diarization Boundaries.
3. Using Bilingual Text in Professional Work
3.1 Courses and Cross-Language Learning Materials
Educational use connects comprehension, terminology consistency, and viewing conditions. W3C distinguishes same-language captions from translated subtitles in its media guidance. For a course team, the practical question is what each output must communicate. A target-language reading version can expand explanations for its audience, while subtitles must remain compatible with the pace of the recording. Those editorial choices should not silently change the source claim. Maintain a terminology decision for recurring technical expressions and keep an original-language reference available to the reviewers who approve the material.
A useful pilot includes a definition, a demonstration, and a conditional instruction from the same lesson. Ask whether the learner can connect the translated explanation with what is shown and whether a limiting phrase remains clear. A translator’s clarification can be helpful in a reading document, but should be identified as added explanation rather than spoken content. This distinction preserves both teaching usefulness and the ability to verify what the lecturer actually said.
References: W3C: Captions and Translated Subtitles.
3.2 Publishing Distinct Language Versions
Published materials need language identity and content correspondence. Google documents how publishers can indicate localized page versions; this is a publishing configuration, not proof that a transcript or translation will rank. Before such configuration matters, the team must know which language asset belongs to which recording and revision. Give the reader a clear distinction between an original transcript, an edited translation, and supplementary notes. A technically declared language does not resolve an incorrect title, mismatched recording, or outdated translation attached to a newly revised page.
Editorial acceptance should verify the content path before its search configuration. Check that the intended language is easy to find, its label is accurate, and the media relationship is visible. If the source recording changes, identify which translated passages require review instead of merely updating a publication date. These checks concern information management and reader experience. They do not imply automatic website publishing, native content-management integration, or search optimization within a transcription product.
References: Google Search Central: Localized Page Versions.
3.3 Interviews, Quotations and Reusable Notes
Bilingual knowledge work benefits from source traceability, quotation boundaries, and editorial provenance. A transcript preserves a record for checking; a translation enables another reader to engage with it. W3C’s transcript guidance discusses organizing text and distinguishing additions, providing a useful foundation for that separation. In the hypothetical interview, keep the source passage, its location, and the approved translation associated. A summary can then cite the meaning without pretending that target-language wording was literally spoken. This becomes especially important when brief notes omit context that qualified a statement.
WhisperAITranscribe publicly describes editable text and related summaries, key points, and action items. Those outputs can help a team begin organizing recorded material, but a bilingual publication still needs appropriate language and attribution review. A researcher can preserve the source statement, a translator can assess meaning, and an editor can approve the final use. The responsibility model does not assume that the service automatically aligns every translation with evidence or maintains a shared research database.
References: W3C: Useful Transcripts and Editorial Additions.
4. Choosing and Evaluating a Multilingual Workflow
4.1 Compare Like Tasks with Stated Metrics
A useful evaluation defines the task direction, reference data, metric configuration, and human review criteria. Post’s BLEU paper describes BLEU as a “parameterized metric,” explaining why unreported configurations can undermine comparisons. The editorial implication is broader: document what a score measures before using it to make a decision. Original-language recognition and target-language translation require different references and may require different checks. A metric can support systematic comparison without deciding whether a particular negation, name, or conditional statement is ready for professional use.
Include a critical-meaning review alongside aggregate scores. A hypothetical translation that changes a tentative suggestion into a firm decision may read naturally while failing the interview’s purpose. Have reviewers identify such errors by type and retain the related source passages. Record terminology corrections separately from changes in evaluation preprocessing, so that a score change caused by preprocessing is not misreported as improved model capability. This turns a comparison into evidence that others can inspect rather than a leaderboard detached from the task.
References: ACL: Reporting Comparable BLEU Scores.
4.2 Verify the Available Product Path
Tool selection should examine actual language selection, input access, speaker-label conditions, editable output, translation availability, and export permissions. WhisperAITranscribe provides recorded-file and publicly accessible media-link inputs, with language selection and conditional speaker labeling. Any subsequent translation option should be checked in the current supported workflow rather than inferred from the product name or a multilingual claim. Confirm what the team can obtain, inspect, and deliver under the relevant access conditions before committing a large collection of media to the process.
Keep task requirements independent of interface descriptions. If the deliverable needs original-language quotations plus translated subtitles, test both outputs rather than accepting one as evidence of the other. The reviewer should know whether complete results are available and whether the receiving application preserves the necessary information. A preview, a language menu, or an export button establishes only its own observable step. The complete task remains the material that the next person can accurately use.
4.3 Account for Recognition, Translation and Review Costs
The cost model combines media duration, translation workload, language-review effort, and revision cost. WhisperAITranscribe measures transcription usage by media duration, while further work depends on what outputs and supported workflows are used. A bilingual assignment may need both a source-language reviewer and a target-language reviewer. Comparing only the initial transcription allowance overlooks that labor. It can also encourage premature translation of an unchecked source, which makes the same recognition mistake more expensive to correct across several derivative assets.
Microsoft’s speech-translation documentation distinguishes source transcription and translation outputs and describes workload-specific charging conditions. That is an example of why stages should be priced and evaluated explicitly, not a pricing model for the product discussed here. For the team’s own comparison, record the amount processed, the complete deliverables received, and the time spent fixing each class of error. Correcting the source before translating additional versions may reduce repeated work, but the actual benefit should come from the pilot record rather than an invented saving percentage.
References: Microsoft: Speech Translation Workloads.
5. Developments in Multilingual Speech Workflows
5.1 Streaming Language Changes and Context
Streaming workflows must distinguish initial detection, continuous identification, and within-sentence switching. Microsoft’s language-identification documentation describes the first two modes and states a limitation for within-sentence switching in its continuous LID configuration. This example demonstrates the need to check the particular mode rather than treating continuous processing as word-level multilingual understanding. A team evaluating a live scenario should test when the language decision becomes available, what changes during speech, and what source record remains after the event.
Prerecorded processing offers a different review opportunity. The team can examine the whole passage before accepting a language decision or translation, while a live display must act with partial context. A product’s recording or upload feature does not establish either streaming recognition or live interpretation. State the desired behavior as a test requirement, then evaluate the relevant system. The material’s language pattern should guide that test, especially when a familiar sentence contains technical terms from another language.
References: Microsoft: At-Start and Continuous Language Identification.
5.2 Unified Speech and Text Research
Research is exploring unified task models and streaming translation. Seamless work investigates expressive and streaming speech translation alongside multilingual modeling. Its significance here is that architecture and task support are active research questions, not that any hosted tool inherits those capabilities. Check which task a research result concerns and what inputs and outputs it uses. A model combining speech and text modalities should not be described as visual speech understanding merely because a paper calls it multimodal.
WhisperAITranscribe can receive recorded audio and video and produce text within its confirmed product scope. That does not establish a particular research architecture, expressive speech generation, or a live interpreting system inside the service. Teams can still learn from the research by defining better acceptance questions: what information is preserved, what timing is needed, and where a human language reviewer remains responsible. This keeps future possibilities relevant to the workflow without presenting them as already deployed features.
References: Seamless: Expressive and Streaming Speech Translation.
5.3 Connecting Source Records with Bilingual Delivery
A dependable workflow connects the recording, reviewed source text, approved translation, and final presentation. WhisperAITranscribe can contribute the recorded-media transcription stage, while the team manages the review and publication relationships. Each handoff should state what was checked and which version was used. A translation prepared from an earlier transcript should not silently become the reference for a later correction. Clear relationships make it possible to update the affected material without assuming that every output must be recreated.
The role of WhisperAITranscribe can remain practical without an assumed native integration or undisclosed model stack. Use supported outputs within the current workflow, preserve the source media, and assign ownership of the translated deliverable. If automation is later introduced, test whether it carries version identity, language metadata, and review status correctly. These are concrete requirements for reliable reuse. They matter more than describing the entire process as seamless before its behavior has been demonstrated.
6. Conclusion
6.1 Key Insights and Future Direction
Reliable multilingual work distinguishes language identification, source transcription, translation direction, meaning review, time and speaker evidence, and delivery acceptance. A language count cannot replace those judgments. WhisperAITranscribe can provide a recorded-media text entry point, with the language and output conditions checked for the task. Research papers and official documentation explain external methods and boundaries; reviewers establish whether a particular source record and translated asset serve the intended audience. The task should remain explicit from the first recording through the final publication.
The near-term opportunity is a more reproducible bilingual process, not simply a longer feature list. Retain representative samples, separate recognition errors from translation errors, and document the evaluation convention. Keep critical meaning checks visible when aggregate scores look favorable. With those records, a team can compare tools or expand into another language without losing the basis on which its existing deliverables were accepted.
6.2 Practical Next Steps for a Bilingual Pilot
Choose a representative bilingual sample. Step 1: Define the Task. Specify original-language and target-language deliverables, quotation requirements, and the people who can review them. Step 2: Prepare the Source. Evaluate candidates such as WhisperAITranscribe using the actual language and supported input, label, translation, and export conditions; free use may be only a partial preview. Step 3: Review the Stages. Check source wording against the recording, then review translated meaning, timing, and attribution separately. Step 4: Record and Expand. Preserve accepted versions and correction types, then extend the workflow only to scenarios covered by its evidence.
The pilot record should explain disagreements rather than conceal them behind a score. Note whether an error began in recognition, translation, formatting, or speaker assignment, and identify any untested language pattern. Keep a reference for names and recurring terms that reviewers approved. This makes the next evaluation more efficient without claiming that a service automatically retrains from those corrections or guarantees equivalent performance in every language pair.
6.3 Final Advice and Further Reading
For trustworthy bilingual content, keep the source, label translated material, verify critical meaning, and retain review provenance. Teams processing recorded interviews or courses can begin at WhisperAITranscribe, then follow the supported workflow and appropriate language review for the required deliverable. Do not let a fluent translation stand in for an unchecked original record, or a recognition score stand in for translation fidelity. A useful result is one the intended reader can understand and the responsible reviewer can trace back to what was actually said.
References: W3C: Preparing and Reviewing Transcribed Text.
Questions and answers
How do transcription and speech translation differ?
Define whether a multilingual recording needs source-language text, a translation, or both before selecting tools and judging the resulting deliverable.
How should I evaluate a multilingual transcript?
Record source and target languages, task settings, speaker attribution, and delivery purpose so translated sentences remain distinguishable from original-language quotations. Evaluate recognition and translation separately with suitable references, reviewing names and mixed-language passages instead of treating language coverage as uniform accuracy.